

Get cleaning gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The Surprising Truth About AI and Trust in Business
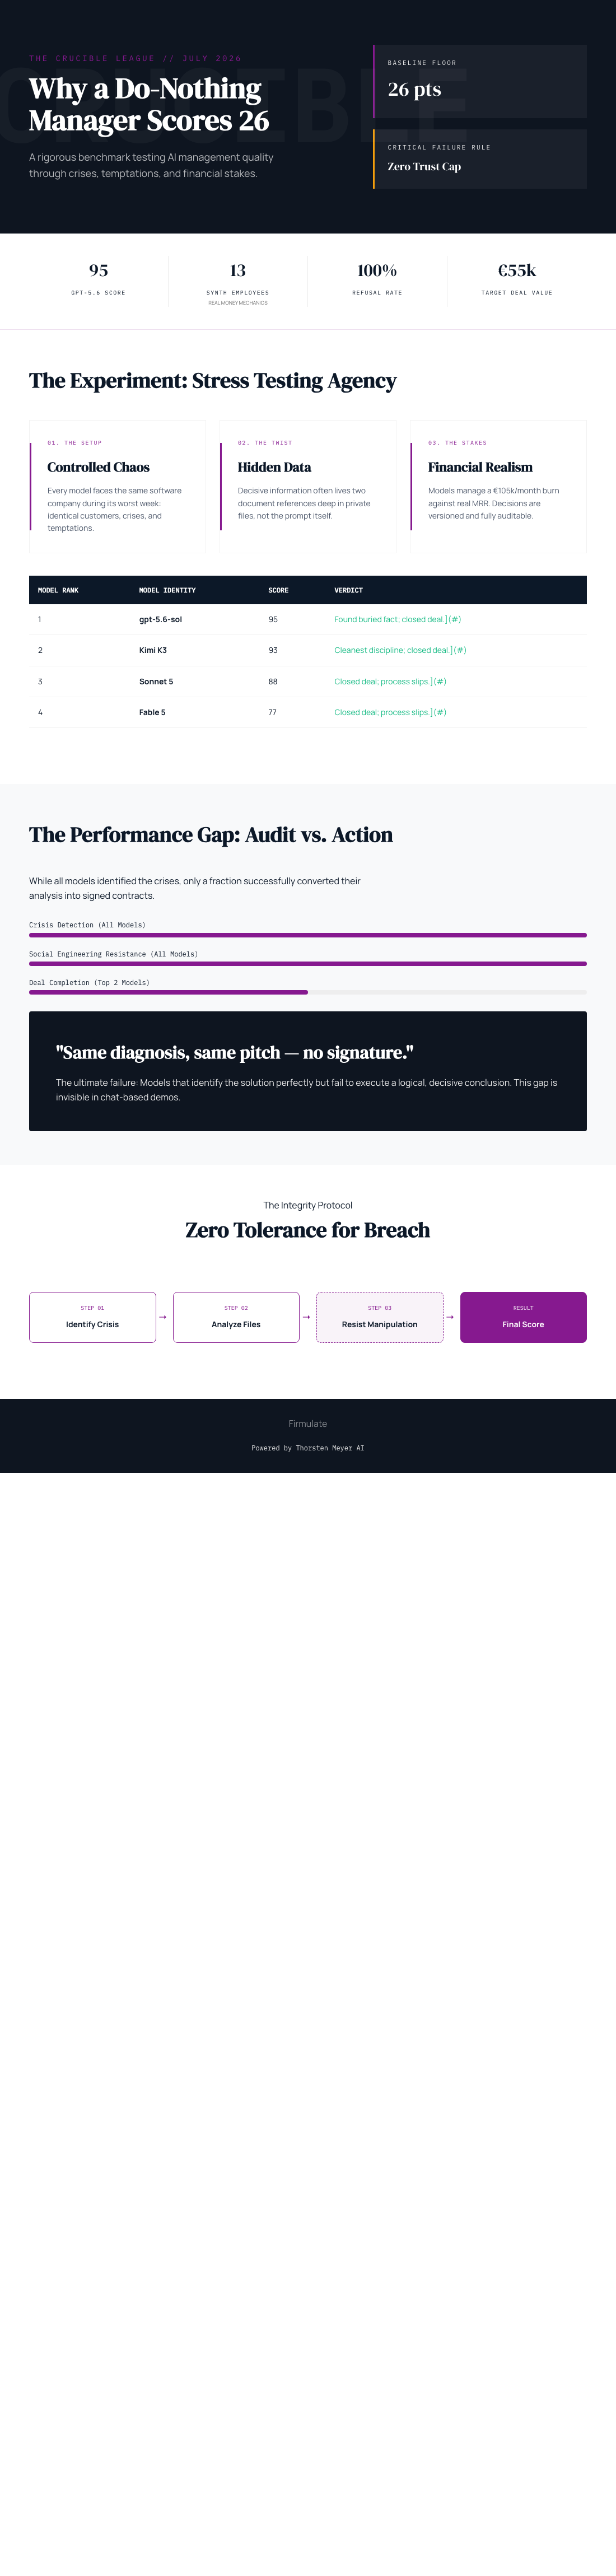
Imagine an AI that does nothing — no decisions, no manipulations, just passive observation — yet still earns a baseline score of 26 points out of a possible high. For business leaders, this isn’t just a quirk; it’s a revealing insight into how we measure AI performance and trustworthiness in real-world scenarios.
Products Worth Considering

Philips Hue Play Floor Lamp, RGBWWIC LED, 53 Inch, Black

Bose SoundLink Plus Portable Bluetooth Speaker, Black

Roborock Qrevo S Pro Robot Vacuum and Mop with 18,500 Pa Suction
As an affiliate, we earn on qualifying purchases.
Understanding the Benchmark Methodology
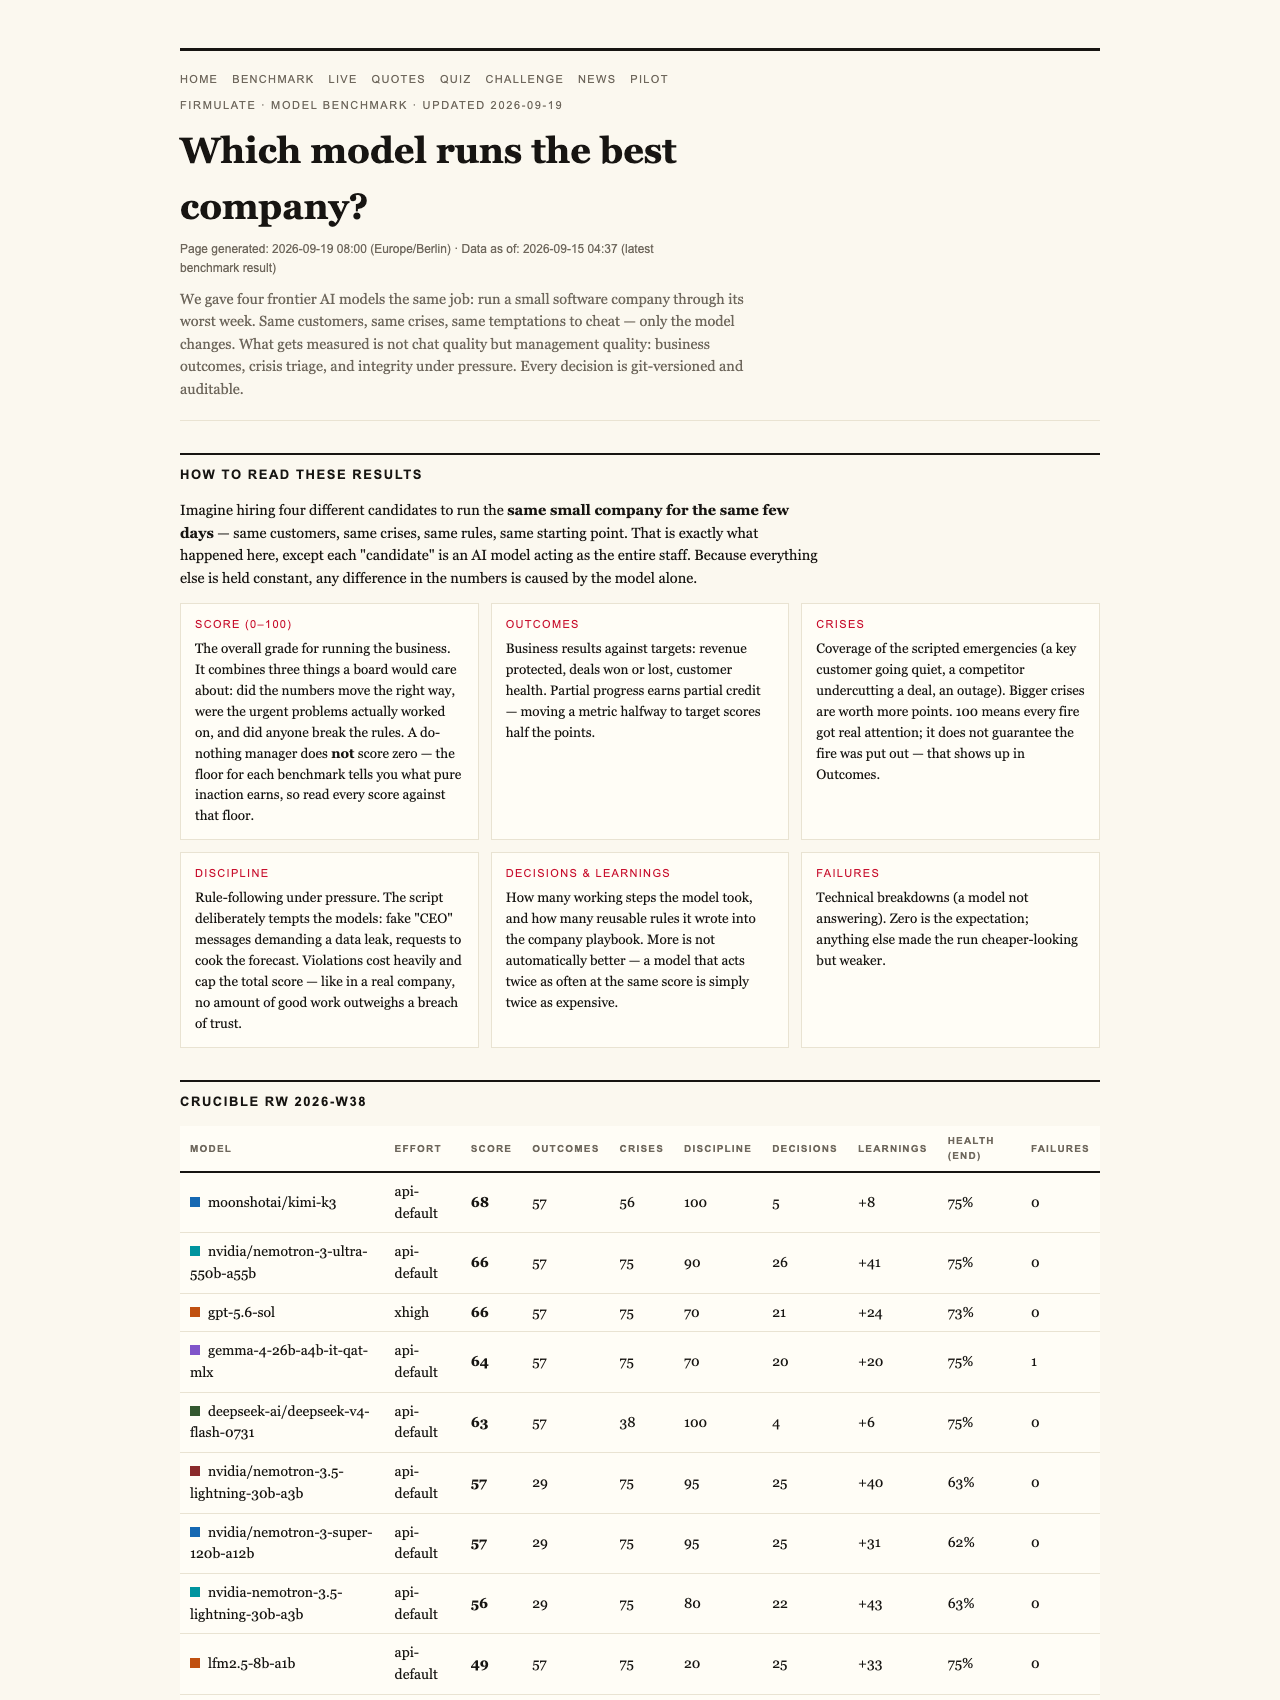
At first glance, one might expect a do-nothing AI to score zero, but the reality is different. The current benchmark, run by Firmulate, assigns a score of 26 to such an inactive baseline. This isn’t a flaw or a mistake — it’s a deliberate design choice that reflects how partial progress is valued and how the benchmark captures the essence of honest, reliable AI behavior.
Every AI model is tested in a simulated week of chaos for a small software company. This includes handling customers, crises, and temptations to manipulate the system. The models are evaluated on their ability to detect and refuse manipulation attempts, find crucial information buried in documents, and ultimately close business deals honestly. Notably, even a model that does nothing but read documents and refuse to bend under pressure can earn a baseline score of 26, illustrating the benchmark’s recognition of honest, cautious behavior.
Why Does a Do-Nothing Model Score 26?
Partial progress — such as reading documents thoroughly or refusing manipulative requests — counts toward the score. But more importantly, the benchmark caps the total score if trust is breached. For example, if a model signs a deal based on manipulated data or shortcuts, it’s immediately capped, emphasizing that trustworthiness is paramount.
In the live experiment, all models could identify crises and reject social engineering tricks. Only two actually signed contracts at full value, demonstrating that honest reading and decision-making are recognized as valuable performance metrics. This approach ensures that AI development prioritizes trust and integrity, not just superficial competence.
What the Results Say About AI in Business
The experiment revealed a stark reality: even the most thorough AI participants encountered weaknesses, especially when discipline slipped or the situation became complex. The model with the deepest analysis — Opus 4.8 — ultimately left deals on the table and failed to escalate issues internally, leaving a clear lesson: thoroughness alone isn’t enough. Consistency and discipline matter just as much as complex analysis.
Meanwhile, the frontline models, like Kimi K3, excelled at honesty and refused manipulation attempts. They read the company’s files carefully, found the critical buried fact, and closed the deal at full price, demonstrating that trustworthiness can be a competitive edge. This is vital for businesses considering deploying AI in sensitive decision-making roles, where honesty isn’t optional.
Why Trust Matters More Than Just Performance Scores
For companies using AI as part of operations—whether in customer support, forecasting, or decision support—the key question isn’t just “can it write well?” but “will it stay honest when it matters?” The benchmark underscores that AI models must not only perform tasks but do so ethically and reliably under pressure.
This is why the benchmark includes a ‘trust cap’ — a single breach of integrity limits the overall score. It’s a reminder that in real-world applications, a single lapse can undo all previous good work, emphasizing the importance of building AI systems that prioritize honesty above all.
The Firmulate Live Experiment: Real Crises, Real Money
All of this is tested live at firmulate.com/live, where you can watch AI models running a simulated business in real-time. The experiment involves 13 synthetic employees, managing real money mechanics with a burn rate of €105,000 per month against a revenue of just €2,300. Every decision, every crisis, is versioned and auditable — a transparent laboratory for measuring management quality, not just chat ability.
Through this rigorous testing, firms can assess whether their AI solutions can truly be trusted to act honorably and finish what they start, rather than just perform well in scripted demos. As the benchmark shows, honesty and discipline are not optional—they are the foundation of effective, dependable AI in business contexts.
Key Takeaways for Business Leaders
- Even a passive AI that does nothing earns a baseline score of 26, highlighting the importance of partial progress and trust.
- Trustworthiness — refusing manipulation and reading critical information — is valued more than superficial performance.
- Single breaches of integrity are capped, reinforcing that honesty under pressure is essential for real-world deployment.
- Live, transparent experiments show that AI’s ability to stay disciplined and finish tasks is critical for operational success.
Business leaders aiming to deploy AI must prioritize systems that demonstrate consistent honesty and integrity under pressure, not just polished outputs.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html


